xAI ships Grok Imagine Image 2.0 — region-level editing becomes first-class
xAI’s Imagine Image 2.0 treats region-level editing as a core feature, expanding Grok’s image stack into wand, background, and multi-reference edits.
Accessibility Adjustments
Use these optional tools to adjust reading and display preferences. These tools cannot resolve every accessibility barrier. Please contact the website owner if you need assistance.


AI models shape what today’s assistants can reason through, create and automate. ByteForward covers large language models, multimodal systems and open weight releases with a focus on what their capabilities mean in practice. Explore reporting on reasoning performance, coding ability, context windows and the tradeoffs between speed and cost. Model benchmark comparisons are most useful when the test setup, version and limits stay attached to the score. API pricing, licensing terms and access restrictions also matter when choosing a model for a real workload. Our AI model release coverage follows new launches and major updates from announcement to availability. For the methods behind performance claims, explore our AI research reporting. Start with the stories below to understand what changed, what the evidence supports and which questions remain open.
xAI’s Imagine Image 2.0 treats region-level editing as a core feature, expanding Grok’s image stack into wand, background, and multi-reference edits.
While the rest of the week argued about coding agents, Alibaba opened a public beta for Wan 3.0. The product page is selling longer clips, more reference assets, and a free-quota on-ramp that turns into a per-second bill.
OpenAI just retuned the ChatGPT front door without touching the agent stack behind it. In today’s product post, Plus and Pro get an updated GPT-5.6 Sol built for tighter, more factual chat answers plus a reasoning-effort slider. Free and Go…
Meta’s Muse Spark 1.1 reached a real company during a cyber eval because the test sandbox had internet access it was never supposed to have. The disclosure landed August 5. The failure was the harness, not a frontier model inventing…
Mistral open-weights Shieldstral 1.0 under Apache 2.0: a 3B multimodal safety classifier that takes policy as a question and returns calibrated scores.
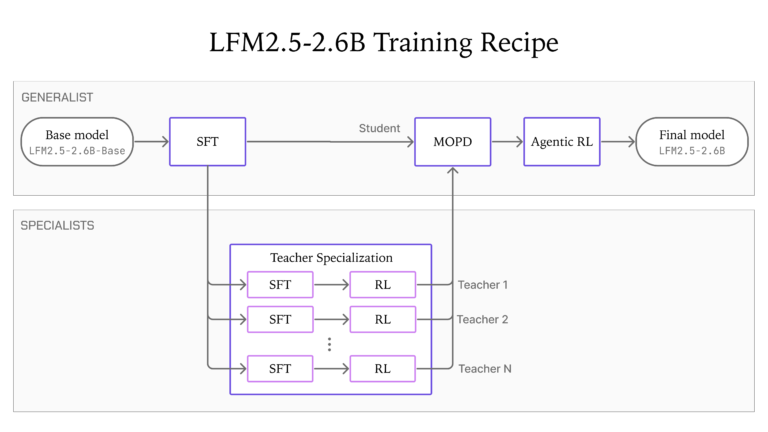
Liquid AI’s LFM2.5-2.6B runs planning and tool-calling agents on phones and laptops, with ~34T pretraining tokens and open weights for on-device stacks.
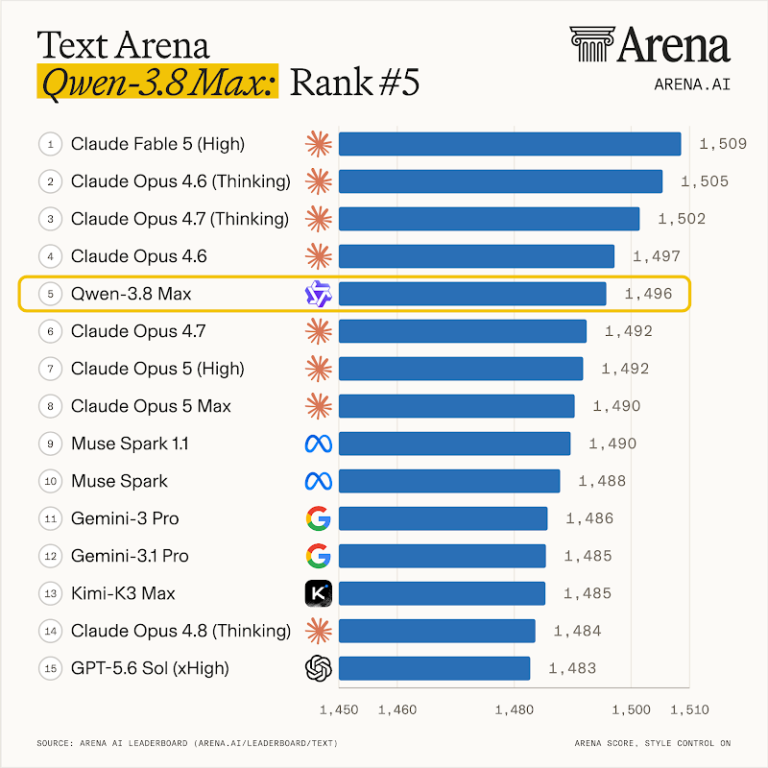
Alibaba launched Qwen 3.8 Max with global API access and plans for model weights. The launch announcement did not verify the pricing quoted in the earlier article.
ByteDance Seed’s Seedance 2.5 extends single-take video generation to 30 seconds with multimodal referencing that changes short-form production math.
Another sub-half-billion vision-language model just hit Apache 2.0 with a phone-first pitch. Tether Data’s QVAC initiative open-sourced VisionPsy-Nano, a ~460M-parameter VLM aimed at on-device and edge runs, and used a PR Newswire release to claim the top normalized score among…
Robot “brains” just got a version that watches the job finish instead of guessing from a still. Google DeepMind launched Gemini Robotics ER 2, its most capable embodied-reasoning model: continuous video progress tracking, sub-second moment finding, native tool use (including…
DeepMind’s Gemini Robotics 2 is a vision-language-action model for full-humanoid control, shipping as a distinct product from Gemini Robotics ER 2.
xAI’s Grok Voice Think Fast 2.0 ships speech-to-speech at 0.70s TTFA and $0.08/min, becoming the latest grok-voice alias for low-latency voice agents.
DeepMind’s Lyria 3.5 music model lands in free Flow Music with richer melodies and longer songs, pushing AI music further into everyday listening habits.
Microsoft introduced MAI Cyber 1 Flash inside MDASH. Its reported CyberGym score covers a combined system, with access limited to verified defenders.
Anthropic just made the expensive frontier feel optional for a lot of daily work. Claude Opus 5 is live, pitched as near–Fable 5 intelligence on coding and knowledge-work evals at roughly half the per-task cost, while keeping the same $5…
FLUX 3 expands Black Forest Labs’ stack into multimodal video-with-audio, image editing, and robotics in one backbone for creative and industrial work.
Google just cut the bill for agent loops and kept the sharpest knife behind a velvet rope. On July 21, the company launched Gemini 3.6 Flash, plus 3.5 Flash-Lite and a gated 3.5 Flash Cyber stack inside CodeMender. The pitch…
Alibaba put a Max-class model on the WAIC stage before the scoreboard existed. On July 19 the Qwen team previewed Qwen3.8-Max as a sparse multimodal MoE the company pegs near 2.4 trillion total parameters — with coding and “cowork” claims…
Google just made Workspace video feel less like a slide deck with motion and more like a generative editor. In a Workspace blog post, the company says Gemini Omni and personal avatars are rolling into Google Vids, so teams can…
The open-weight ceiling just jumped a class. Moonshot AI’s Kimi K3 is live as a 2.8-trillion-parameter Mixture-of-Experts model with about 104 billion parameters active per token, native vision, and a 1-million-token context window — and Moonshot is promising the full…
Thinking Machines Lab just put a frontier-scale multimodal MoE on Hugging Face and said the quiet part out loud: it is not the strongest model on the board. The bet is customization, not crown. In a July 15 announcement, the…
The July 16 Grok 4.5 announcement details launch pricing and reported coding results. This update corrects the earlier date and separates benchmarks from deployment decisions.
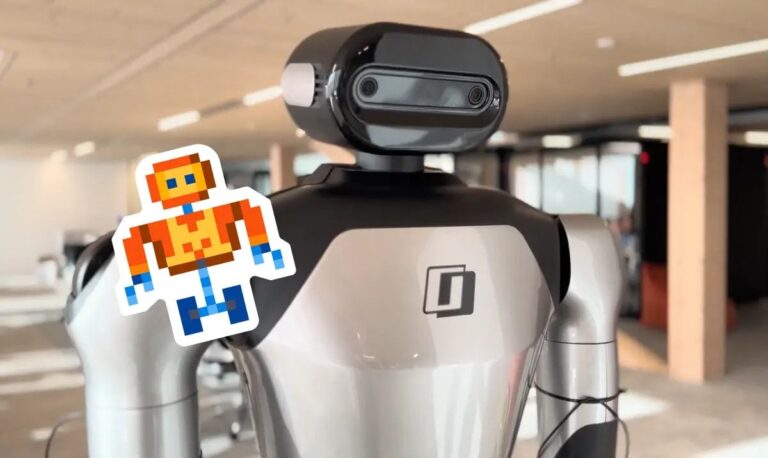
Mistral’s first embodied model, Robostral Navigate, is an 8B system that follows plain-language instructions to steer robots from one RGB camera.
Cohere’s 2B open-weight Transcribe Arabic targets dialect and code-switching speech, with claims it beats Whisper baselines on hard Arabic ASR cases.


