RobotWorld tests AI agents across 84 simulated tasks

Five models leave 63 tasks unsolved in the reported evaluation.
Accessibility Adjustments
Use these optional tools to adjust reading and display preferences. These tools cannot resolve every accessibility barrier. Please contact the website owner if you need assistance.



Five models leave 63 tasks unsolved in the reported evaluation.

Ai2 announces Qwen and Llama based byte model checkpoints alongside its Nature paper, with Stage 1 models for research.

Perplexity’s smaller retrieval model can query an index built with its larger counterpart.
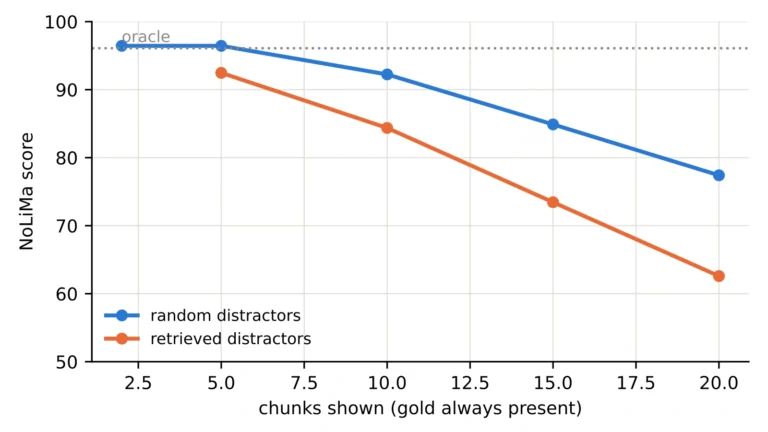
A research framework links corpus retrieval with long context reasoning.
A new benchmark separates safe task completion from efficient resource use.
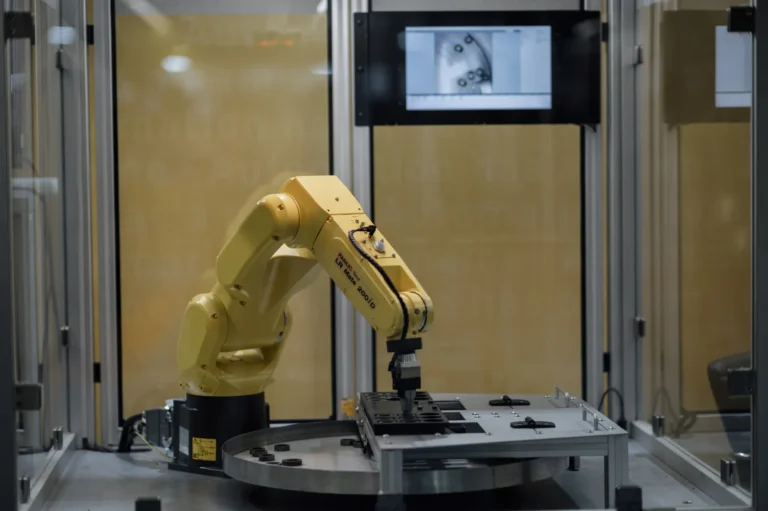
A robot study tests physical feedback without adding tactile sensors.
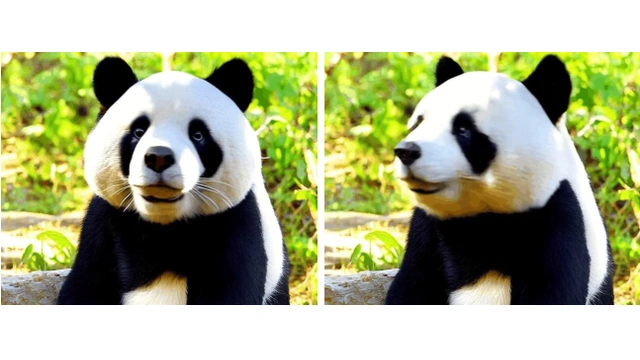
A new preprint studies motion transfer while limiting copied appearance.
A preprint tests what electricity measurements can establish about computation.
Anthropic said Haiku 5.5 would arrive in the coming weeks on September 28. The exact date, pricing and public access details remain unconfirmed.
A conceptual preprint examines feedback between AI systems and human culture.
Nearly half of respondents to the trust question trust AI when they can check its output.
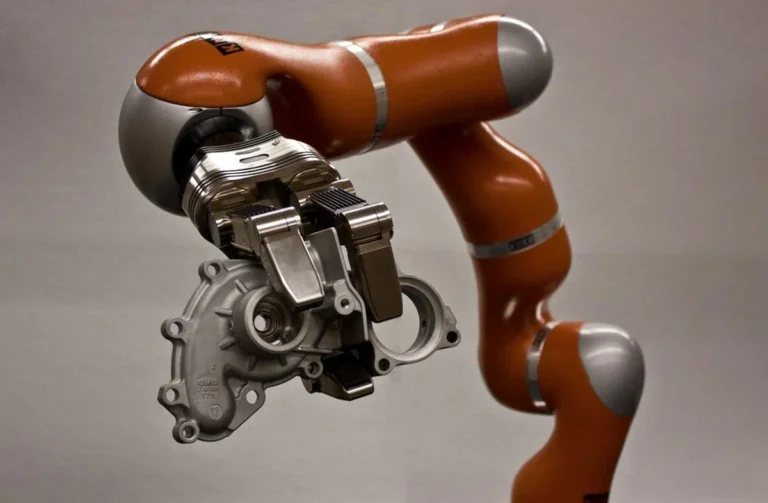
A new preprint evaluates robot task completion and refusals using an existing open source framework.
Stanford researchers test more selective robot practice with human supervision.
OpenAI shares hundreds of mathematics manuscripts while warning that formal verification coverage varies across the collection
Researchers test synthetic video detection across 46 generator variants. Code and model releases remain pending.
A new preprint tests selective memory processing across five benchmarks, with latency and privacy limits still important.
Research preview measures missed issues and noisy findings.
ByteForward’s launch analysis examines specialist results, API pricing and the checks that matter before adding Mistral Large 4 to a workflow.

An arXiv preprint separates answer corrections from agreement under pressure.
An 11 task research evaluation compares Astra and Sol on contracting workflows.
The 740 million parameter release combines text, image, video and audio embeddings for local retrieval.
New analysis explains why copied solutions escaped checks and how exposure changes proxy benchmark scores.
Nano Banana 2.1 is available in the Gemini API. Google’s current documentation lists no shutdown date for the older Nano Banana 2 model.
An expanded HuatuoGPT 3 paper reports medical benchmark gains while warning that clinical validation remains necessary.