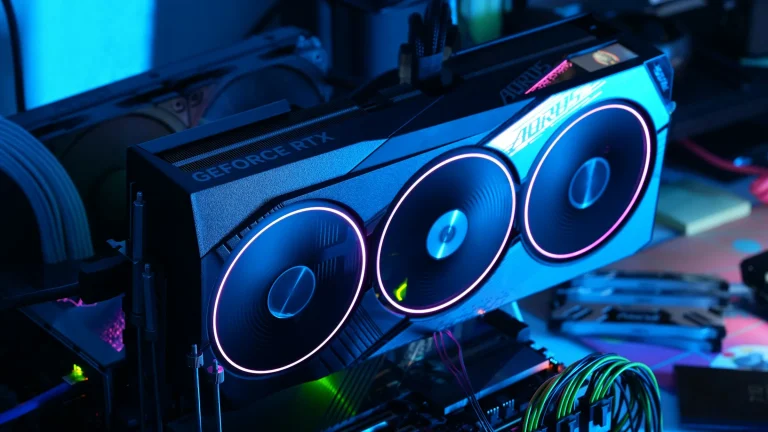
llama.cpp improves selected GPU inference paths for low bit models
A merged llama.cpp optimization brings hardware specific gains. Here is what the measurements show and how to check whether your setup benefits.
Accessibility Adjustments
Use these optional tools to adjust reading and display preferences. These tools cannot resolve every accessibility barrier. Please contact the website owner if you need assistance.


A merged llama.cpp optimization brings hardware specific gains. Here is what the measurements show and how to check whether your setup benefits.
Qwen Code 0.25.1 expands side conversations and approval previews. A later background agent change has a separate availability boundary.
The experimental runtime now has Windows and Linux packages. NVMe storage and available memory still shape what it can run and how well it performs.
Precision Numerics releases binary weights and local runtimes with developer reported quality tradeoffs.
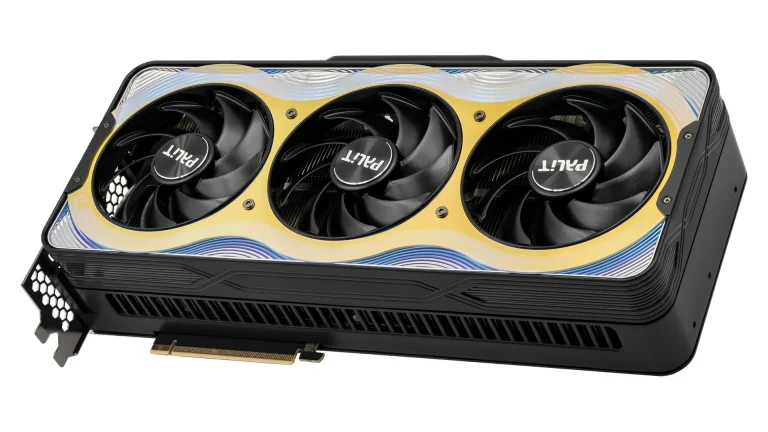
What to check before running the new local Qwen engine.
The October 2 hosted API addition supports transparent images and editing with up to ten references.
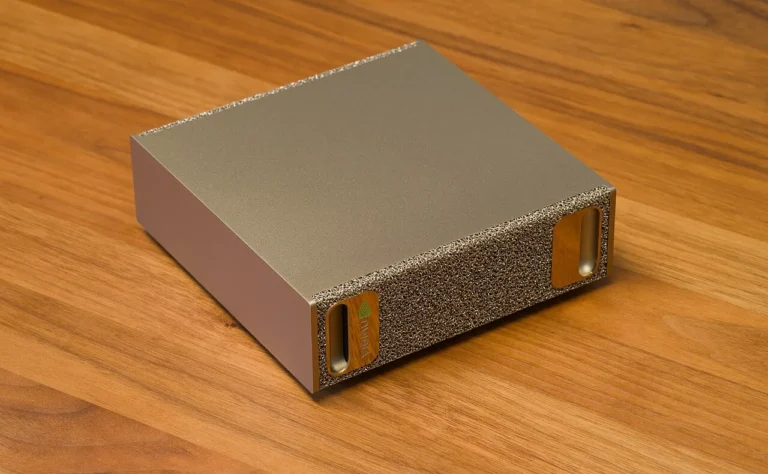
The partner configuration keeps GB10 while cluster setup and model deployment remain separate steps.
A September 30 SGLang draft targets Huawei Ascend attention support around the Qwen 4 architecture preview. Complete model serving still needs validation.
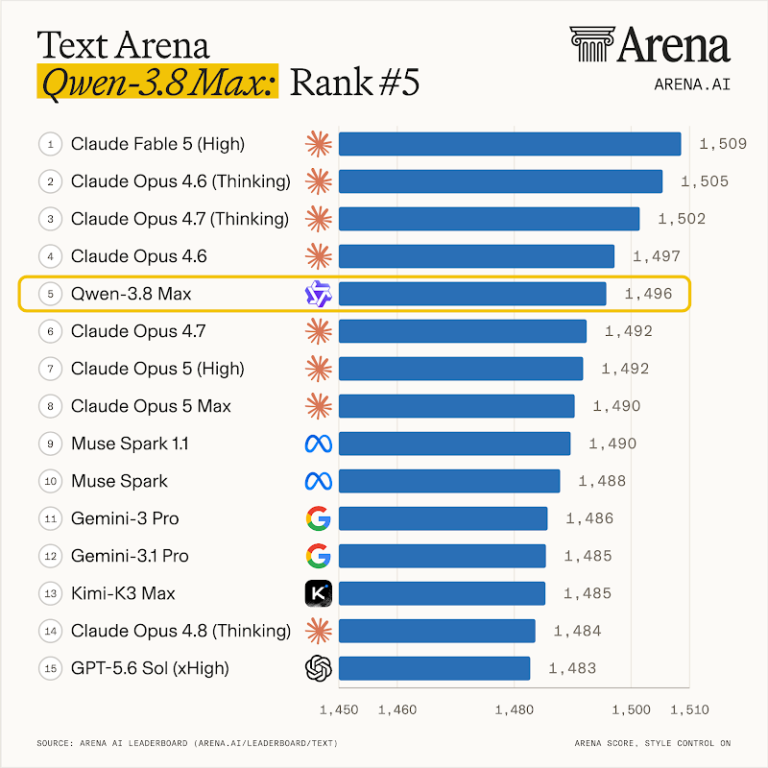
Alibaba launched Qwen 3.8 Max with global API access and plans for model weights. The launch announcement did not verify the pricing quoted in the earlier article.


