Perplexity releases two models for text and image search
Perplexity’s smaller retrieval model can query an index built with its larger counterpart.

Perplexity announced two new retrieval models on October 7 for searching text, images and visual documents. The release targets the step that finds relevant material before an AI system uses it to answer a question. Perplexity announcement
The 0.6B and 9B versions share an embedding space. Each produces 128 dimensional token vectors and scores retrieval with MaxSim. The smaller model can search an index built with the larger one. That compatibility could give developers more flexibility when choosing which model handles queries. Perplexity model card
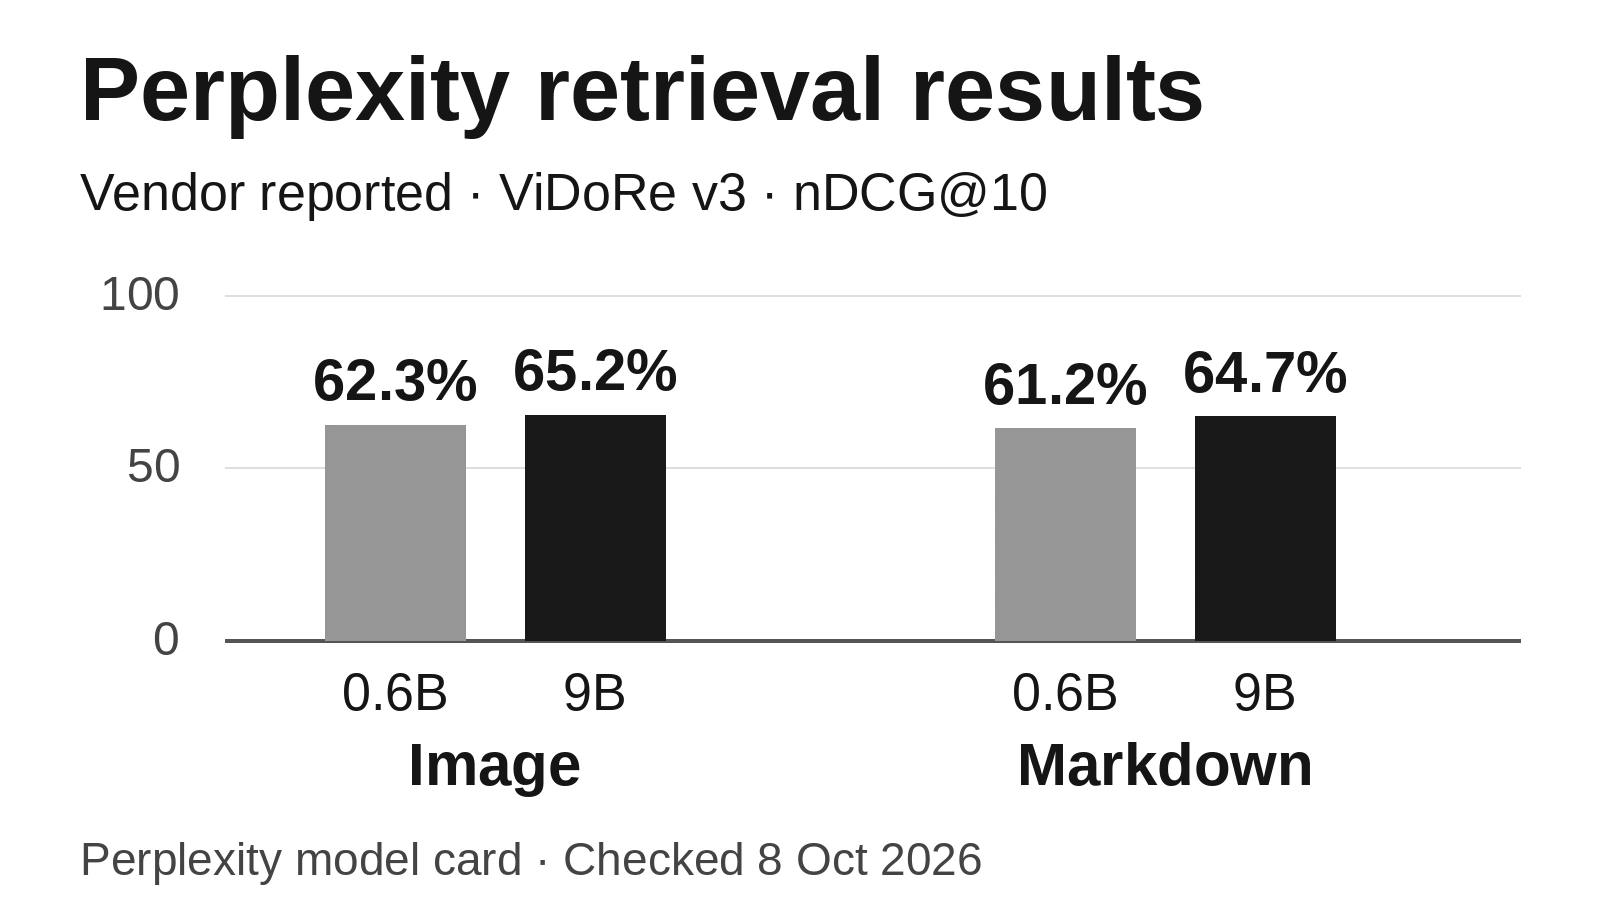
The company’s ViDoRe v3 table puts the larger model ahead for both inputs. These are vendor reported nDCG@10 ranking scores. ByteForward has not reproduced the tests. Perplexity model card
One practical restriction matters. Text and image inputs must be encoded in separate batches. Teams should check that constraint against their document pipeline before substituting the models into an existing search system. Perplexity model card
The benchmark table offers a narrow starting point. It does not establish production latency, deployment cost or performance on a team’s own files. Those questions need workload specific testing.
For related developer uses, read our coverage of Perplexity’s Decider classification model.
Original chart of vendor reported ViDoRe v3 ranking scores. Higher is better. ByteForward has not reproduced the tests. Source model card