Fish Audio releases Drama 3 with finer control over AI voices

Fish Audio released Drama 3 on October 13, bringing a speech model with downloadable weights and more detailed performance controls to its website, mobile apps and API. Its interactive editing tools remain in limited testing.
Directing the delivery
The product documentation describes a script that carries both dialogue and direction. Creators can place an emotional instruction before a line, insert a breath or pause, and apply a particular delivery to selected words. Directions can use a different language from the spoken text.
A scene can contain multiple speakers in one request, with a separate reference voice for each. Pronunciation controls can specify how a name should sound. Switching languages within a line is still described as experimental, with results depending on the voice and language combination.
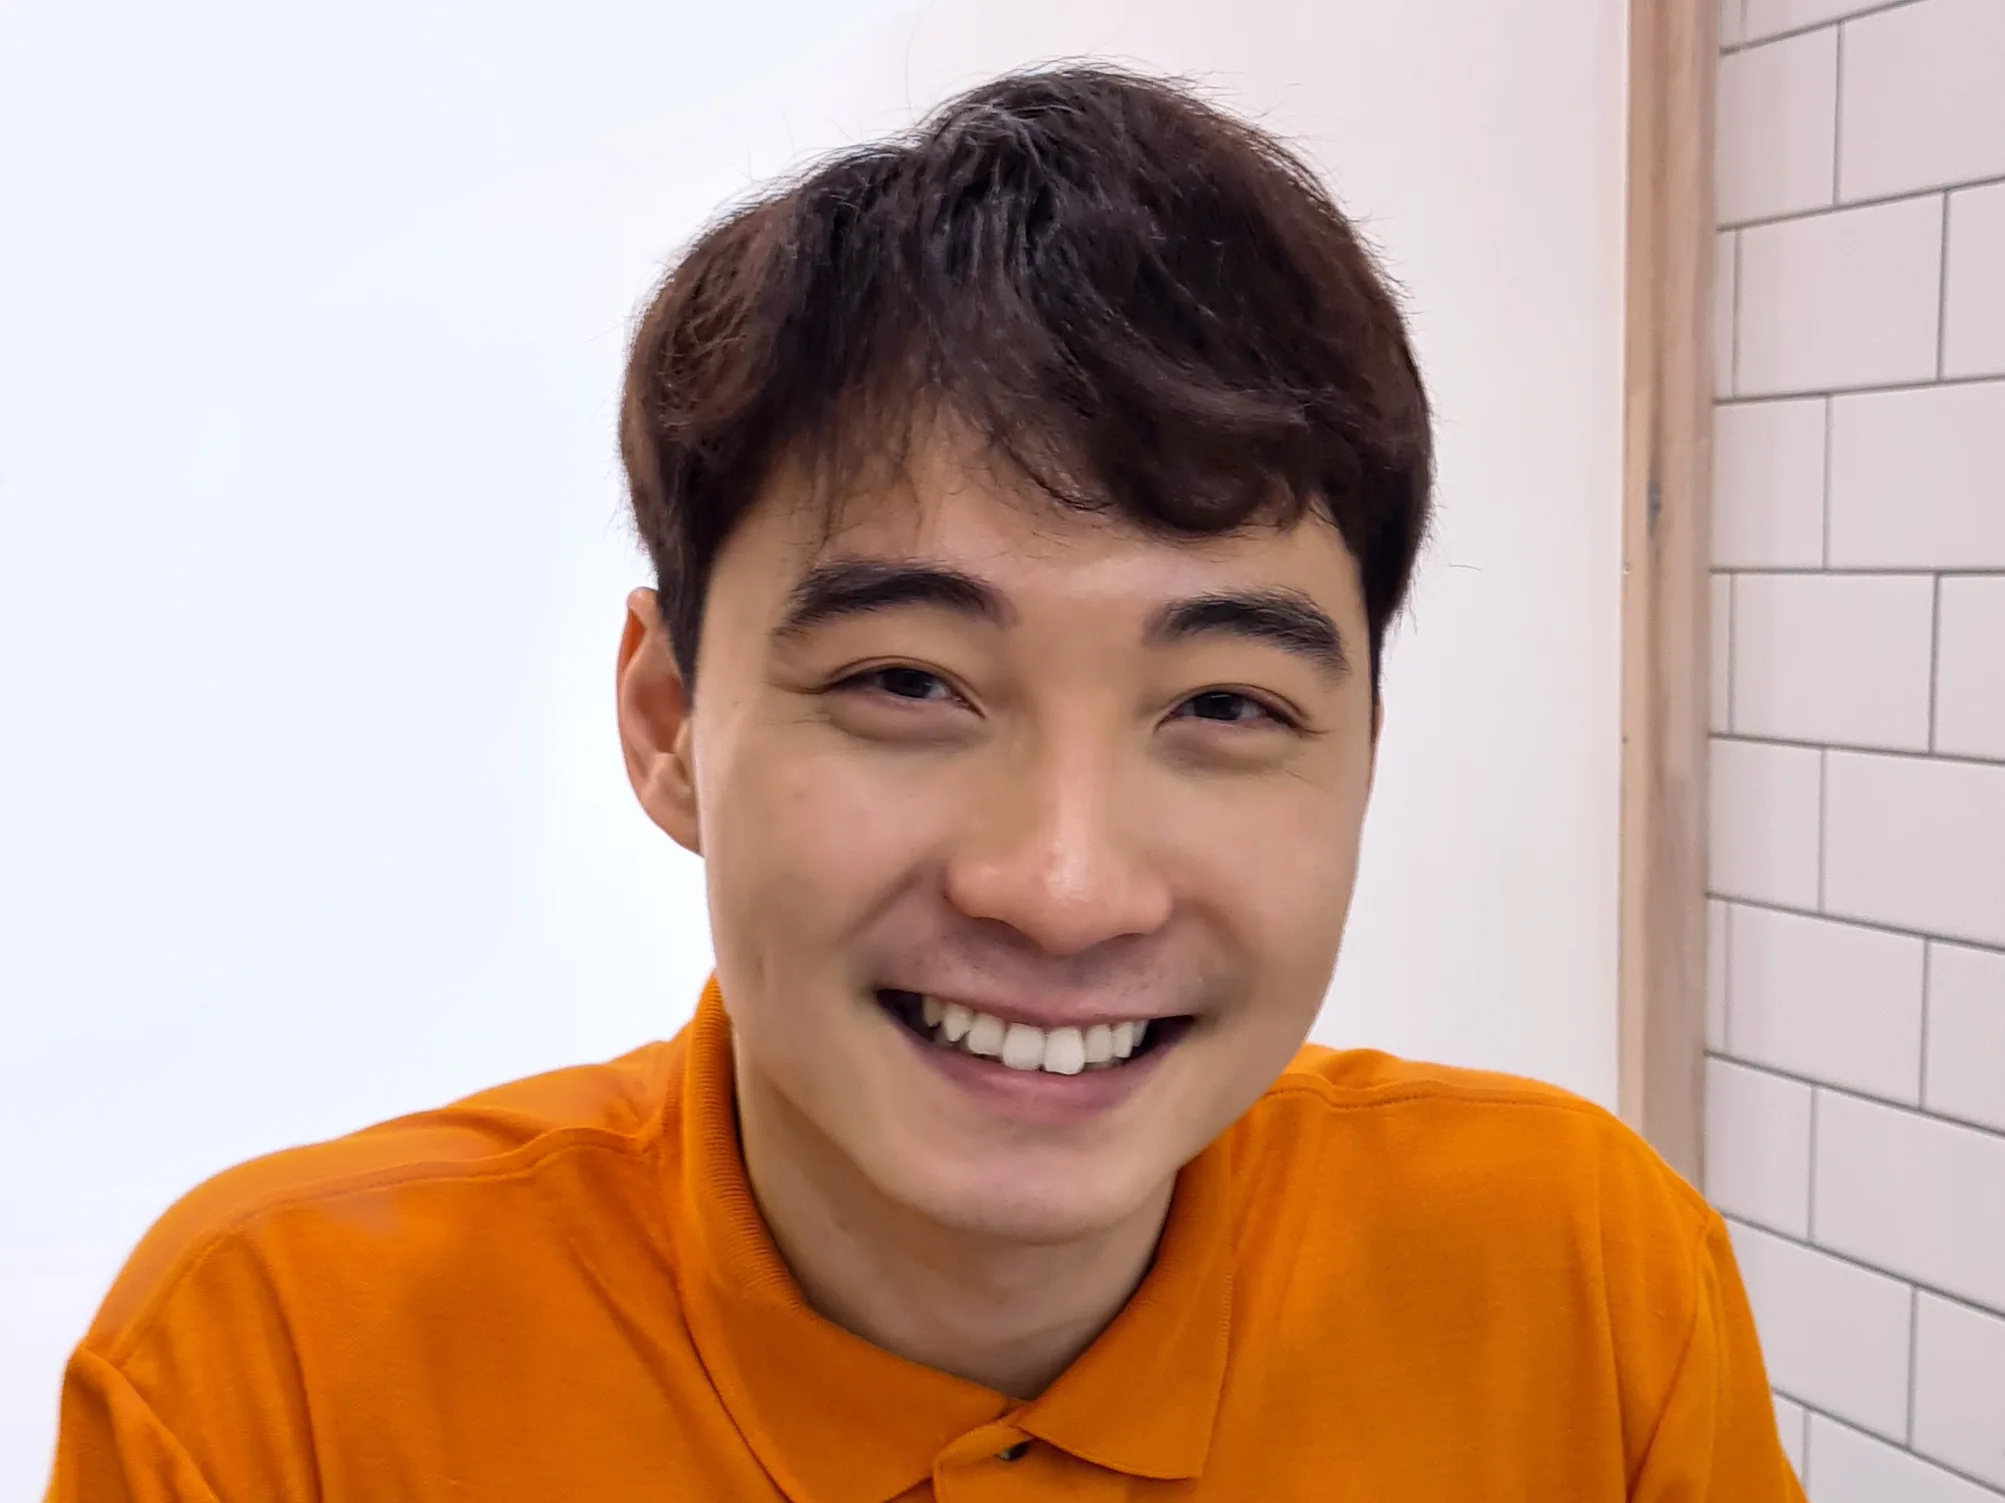
The launch demonstration features Uncle Roger directing a clone of his own voice. Fish Audio says it was made and used with his permission.
Downloadable weights with practical limits
The official model card describes a mixture of experts backbone with 35 billion parameters and about 3 billion active for each token. It combines full and linear attention with a decoder that predicts ten audio codebooks. Speaker tags support up to 16 characters, while longer text can be divided automatically and streamed in chunks.
The repository provides FP8 expert weights with other weights in BF16, plus a deployment route through SGLang Omni. These are concrete public artifacts. ByteForward has not run the model locally or independently verified its performance.
For a production team, the useful comparison is the complete workflow. Hardware capacity, voice references, retries and listening time all belong in a trial. A lower count of active parameters should not be treated as a promise that a model will fit a particular machine.
Commercial access comes with conditions
The Fish Audio Community License, updated October 13, permits research and noncommercial use and allows qualifying commercial users below $500,000 in combined annual gross revenue to operate without a separate commercial agreement. Affiliates count toward that threshold.
Hosted speech generation services require a separate written agreement, subject to the license’s defined exceptions. Delivering finished audio to a client is treated differently from giving that client automated access to generate it. The terms also restrict deceptive impersonation and require consent or another legal right to imitate an identifiable person’s voice.
Editing demos are ahead of general access
Fish Audio’s announcement places interactive revision and audio inpainting in small, invitation only tests. Its demonstration replaces a selected word while preserving the surrounding recording. A dedicated editing API is still forthcoming. Those demos do not establish general access to those tools.
Quality needs more than a launch sample
Artificial Analysis’s pronunciation methodology uses fixed sentences with difficult spans and accepted readings. Reviewers hear anonymized clips and judge whether the marked text is pronounced correctly. The test covers names, context dependent readings, exact sequences and shorthand. It is a different question from whether an entire dramatic performance feels convincing.
A useful studio trial would keep the voice and script fixed, vary one direction at a time, and check both expression and the spoken words. For a longer project, listen across scene boundaries and revisions. The release gives creators more controls to examine. Whether those controls reduce production work needs testing on their own material.