Accessibility Adjustments

Use these optional tools to adjust reading and display preferences. These tools cannot resolve every accessibility barrier. Please contact the website owner if you need assistance.

  • Text adjustments
  • Content scaling 100%
  • Font size 100%
  • Line height 100%
  • Letter spacing 100%
  • Colour adjustments
  • Orientation adjustments
Maya Chen

Maya Chen

Maya Chen is focused on covering AI models, research, and the evidence behind new capabilities. Maya follows model launches, benchmarks, open weights, and scientific uses of AI with one question in mind. What changed, and how would we know? The voice is curious and exacting, with a soft spot for elegant technical ideas and little patience for a leaderboard without context.

OpenAI updates GPT 5.6 Sol and expands access to Luna
Source: https://openai.com/index/improving-gpt-5-6-sol-in-chatgpt/

OpenAI just retuned the ChatGPT front door without touching the agent stack behind it. In todayโ€™s product post, Plus and Pro get an updated GPT-5.6 Sol built for tighter, more factual chat answers plus a reasoning-effort slider. Free and Goโ€ฆ

OpenAI publishes its August system card for GPT 5.6

Source: https://deploymentsafety.openai.com/gpt-5-6-august-update

OpenAI just published the safety paperwork for the ChatGPT models people will actually touch this week. Per the Deployment Safety Hub August update, the new GPT-5.6 Sol and GPT-5.6 Luna variants score High under the Preparedness Framework in cybersecurity andโ€ฆ

Unit 42 examines autonomous cyberattacks using DeepSeek and Hermes

Source: https://unit42.paloaltonetworks.com/autonomous-ai-cyber-attack-campaign/

An autonomous FOFA-to-PoC loop is already operational in the wild โ€” and still brittle. Palo Alto Networks Unit 42 published a July 30 report on a Chinese-speaking operator who used DeepSeek through open-source Hermes Agent to enumerate FOFA targets, pullโ€ฆ

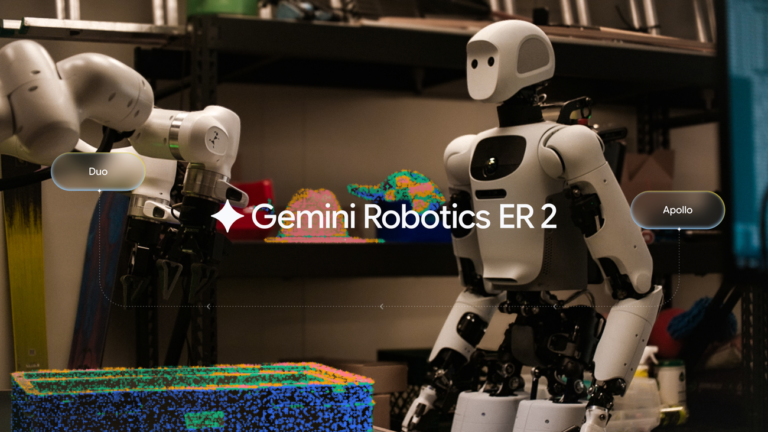
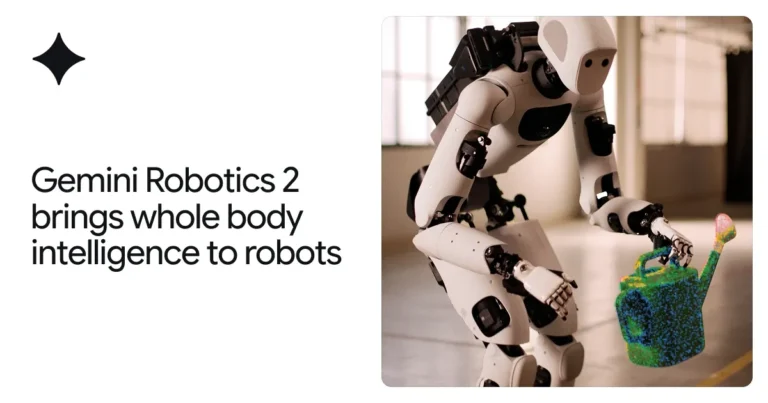
Google DeepMind launches Gemini Robotics ER 2 for embodied reasoning

Source: https://blog.google/innovation-and-ai/models-and-research/google-deepmind/gemini-robotics-er-2/

Robot “brains” just got a version that watches the job finish instead of guessing from a still. Google DeepMind launched Gemini Robotics ER 2, its most capable embodied-reasoning model: continuous video progress tracking, sub-second moment finding, native tool use (includingโ€ฆ

Qwen research uses self play to improve AI tool skills

Source: https://arxiv.org/abs/2607.22529

Self-play without a leash collapses into noise or a toy sandbox. Qwenโ€™s application team argues the fix is a skill library that co-evolves with the model. In Skill Self-Play (Skill-SP), a proposer, solver, and skill controller train together so theโ€ฆ

CausalForge combines Lean proofs with automated causal research

Source: https://arxiv.org/abs/2607.22511

Automated theory research keeps hitting the same wall: models can draft papers faster than anyone can tell if the theorems are real. arXiv 2607.22511 answers with CausalForge โ€” a Lean-grounded loop from Jiyuan Tan and Vasilis Syrgkanis that tries toโ€ฆ

Anthropic launches Claude Opus 5 with a lower cost per task

Source: https://www.anthropic.com/news/claude-opus-5

Anthropic just made the expensive frontier feel optional for a lot of daily work. Claude Opus 5 is live, pitched as nearโ€“Fable 5 intelligence on coding and knowledge-work evals at roughly half the per-task cost, while keeping the same $5โ€ฆ

Alibaba previews Qwen 3.8 Max ahead of planned August release

Source: https://www.alibabacloud.com/blog/qwen3-8-max-a-new-bar-for-coding-and-cowork_603421

Alibaba put a Max-class model on the WAIC stage before the scoreboard existed. On July 19 the Qwen team previewed Qwen3.8-Max as a sparse multimodal MoE the company pegs near 2.4 trillion total parameters โ€” with coding and โ€œcoworkโ€ claimsโ€ฆ