

Z.ai releases GLM 5.3 with reported gains on coding tasks
Z.ai says GLM-5.3 uses the same base model as GLM-5.2. The jump is post-training: more finished coding jobs, longer tasks, and cyber scores that moved faster than the lab expected. Open weights are promised in two weeks, after safety work.

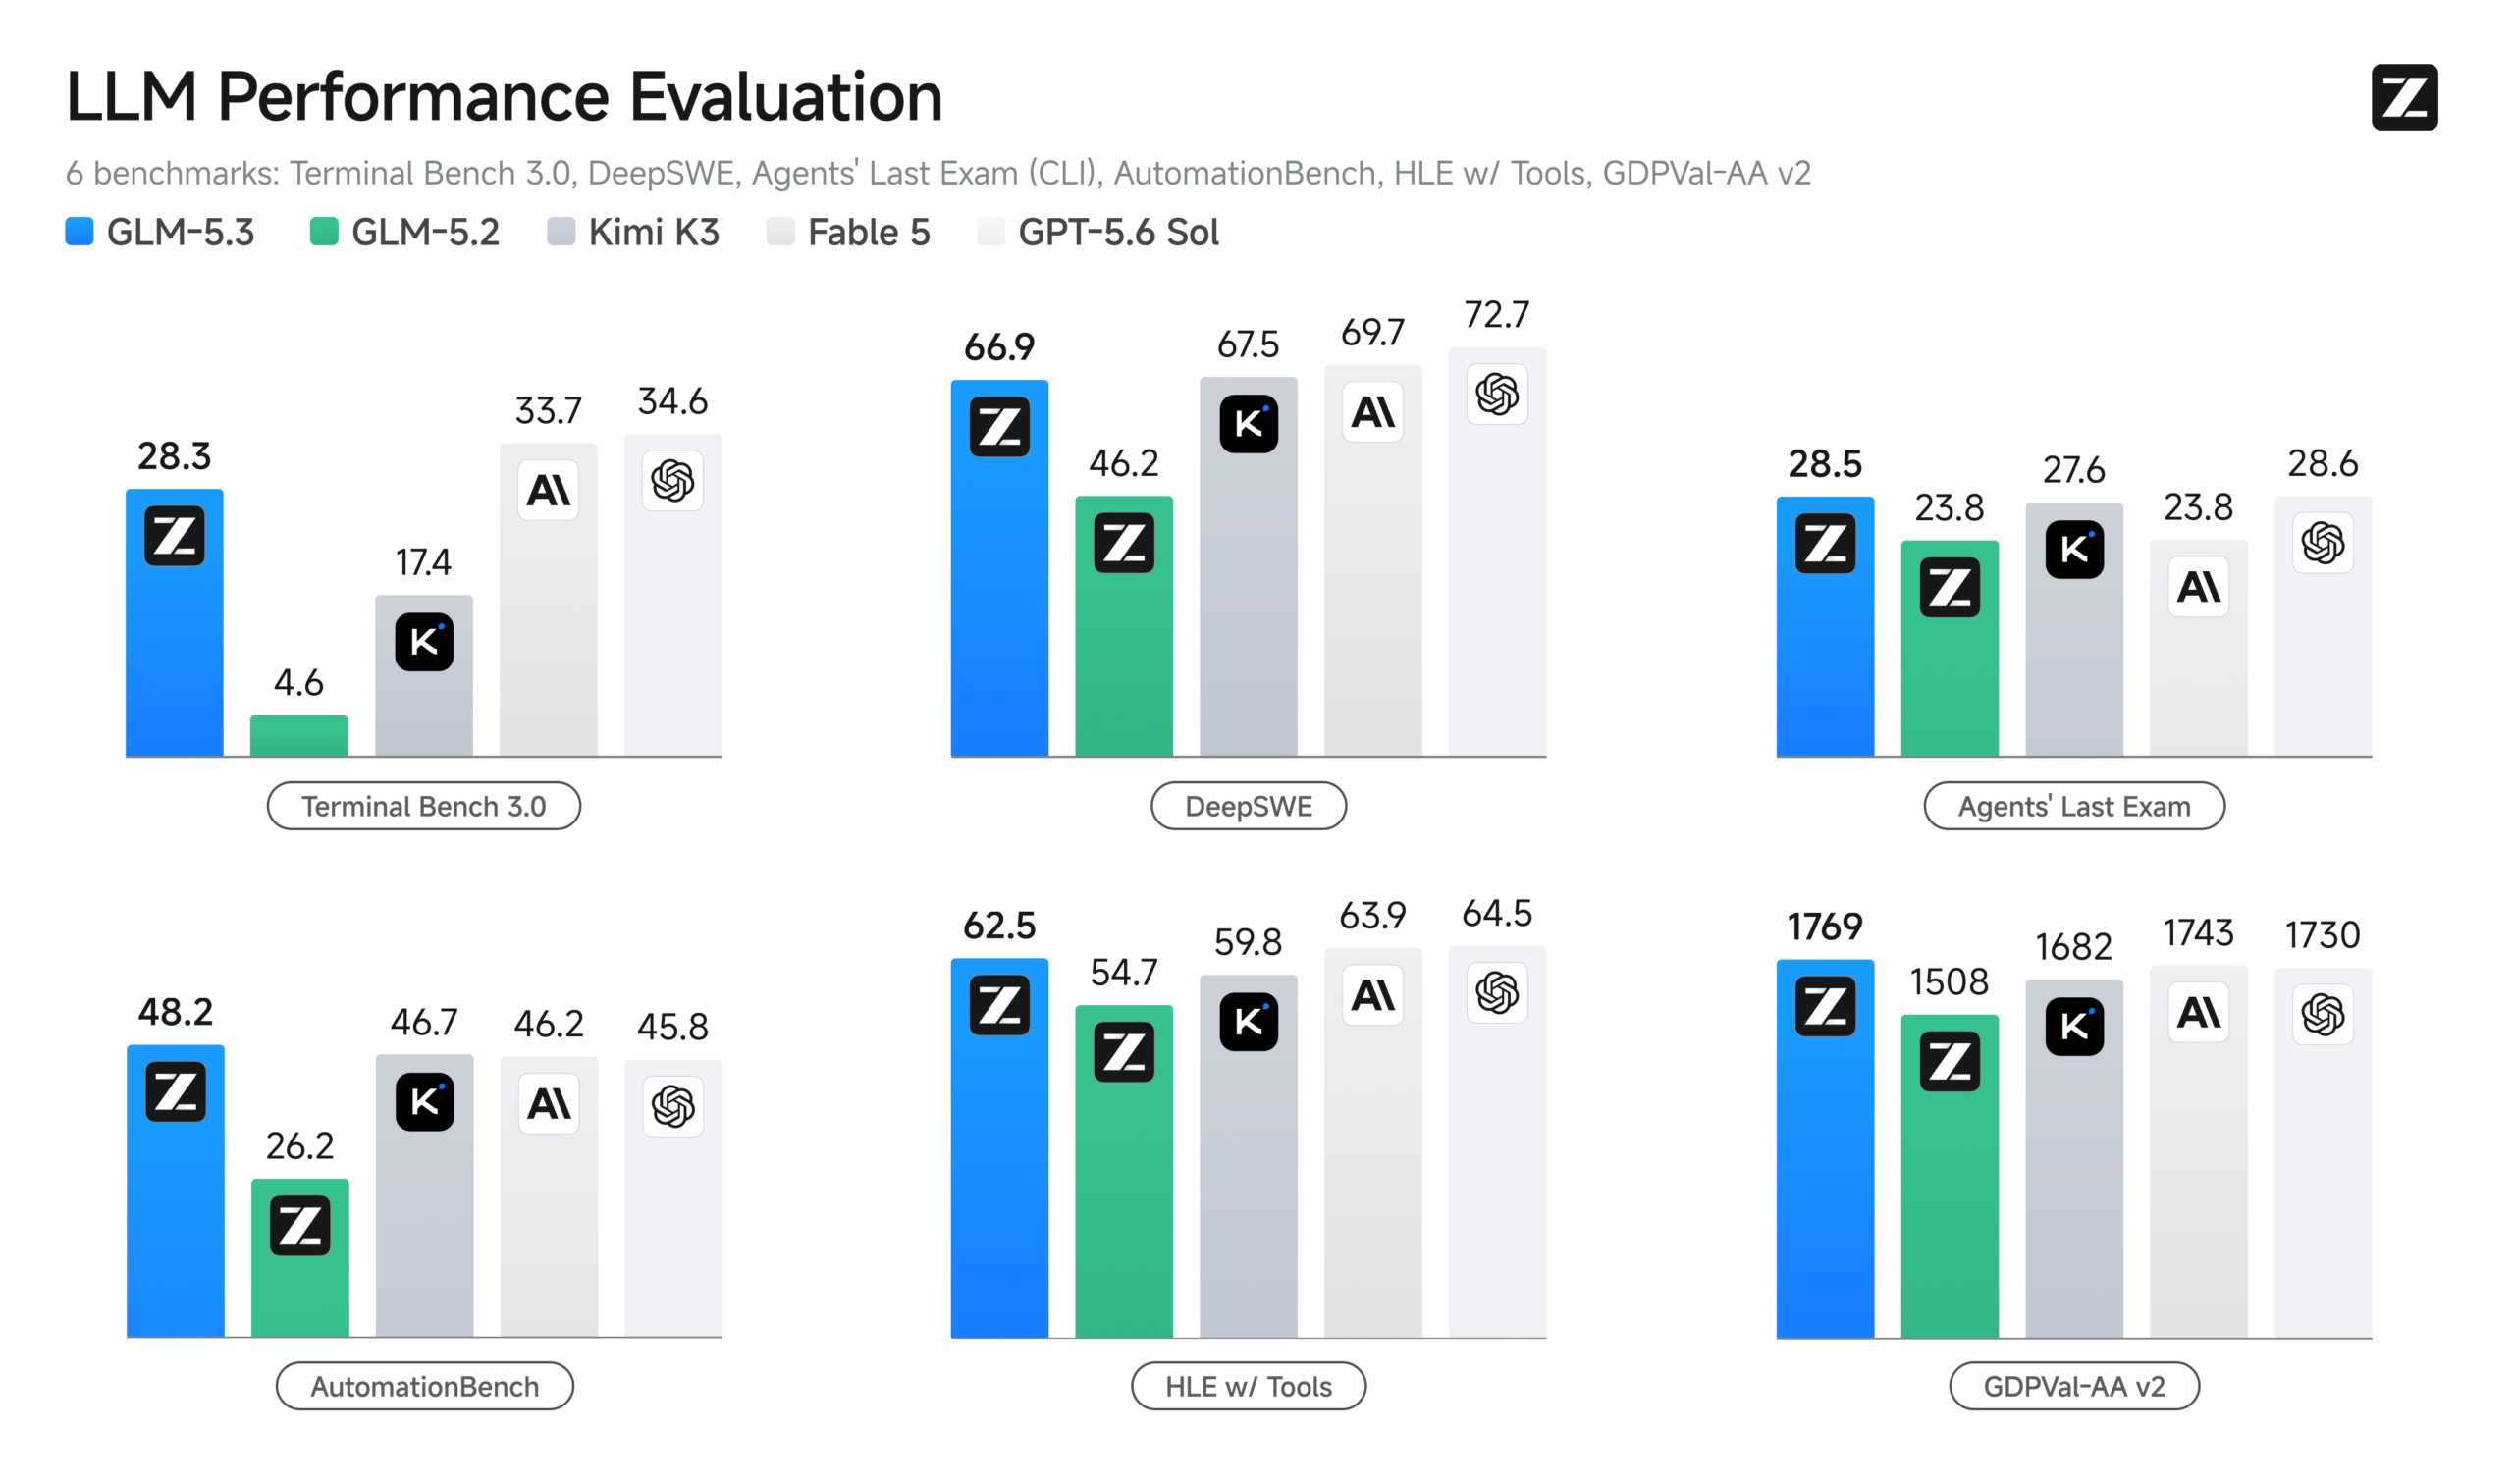
Z.ai did not ship a new brain. Per the August 14 launch post, GLM-5.3 uses the same base model as GLM-5.2. Every gain the company is selling comes from a month of extra post-training on long jobs.
What actually got better
The useful translation is not the model card. It is whether the model can sit in a real repo, keep going, and finish. Z.ai says GLM-5.3 is much stronger at complex coding and long-horizon work than 5.2. On the public tests it chose to highlight, Terminal-Bench 3.0 moves from 4.6 to 28.3. DeepSWE v1.1 moves from 46.2 to 66.9. Agents’ Last Exam moves from 23.8 to 28.5.
Those are Z.ai-reported numbers, on Z.ai’s chart, against a field that includes Kimi K3, DeepSeek V4 Pro 0813, Claude Opus 4.8, Fable 5, and GPT-5.6 Sol. On that same chart, GLM-5.3 still trails the closed frontier on several coding suites. The story is the jump from 5.2, not a coronation.
The in-house coding test
Z.ai also published a private suite, Z.ai Code Bench, built to look more like a local development job than a leaderboard puzzle. At Max effort, the company says GLM-5.3 finishes 34.5% of those tasks at about 75K output tokens, versus 23.4% at 96K for GLM-5.2. At High effort it claims 31.4% at about 50K tokens, ahead of Claude Opus 4.8 at 29.5% with 120K. Fable 5 still leads that private chart at 39.5% Max.
If those token counts hold outside the lab, the model is not only completing more of the job. It is burning less text to get there.
Cyber moved faster than they planned
The same post is unusually blunt about security. Z.ai says cyber capability emerged faster than expected while they scaled post-training. GLM-5.3 is listed as state of the art on CyberGym for vulnerability discovery, and the company says it more than doubles GLM-5.2 on exploitation benchmarks. ExploitBench is shown moving from 24.4 to 54.4. ExploitGym jumps from 29/39 to 105/130 under the two compute budgets on the chart.
That is the part that should make buyers slow down, not speed up. A coding model that also climbs the exploit chain is a product and a policy object at the same time.
Open weights, later
Z.ai says the weights will be released two weeks after launch, once safety evaluation and hardening are done. Until then this is an API-and-demo story with a promised dump. Treat the open-source claim as a date, not a file on disk.
Analysis: if the Terminal-Bench jump survives independent runs, GLM just turned a point release into a coding-agent story. If the cyber scores are the real tell, the industry is going to argue about whether that is a feature or a reason to gate the weights. Watch the two-week dump, and whether anyone outside Z.ai can reproduce the 4.6-to-28.3 leap.
Watch the ByteForward breakdown: GLM 5.3 Is OUT — The Jump From GLM 5.2 Is Huge.



