

UNREAL uses a language model to select its own evidence
A research framework links corpus retrieval with long context reasoning.

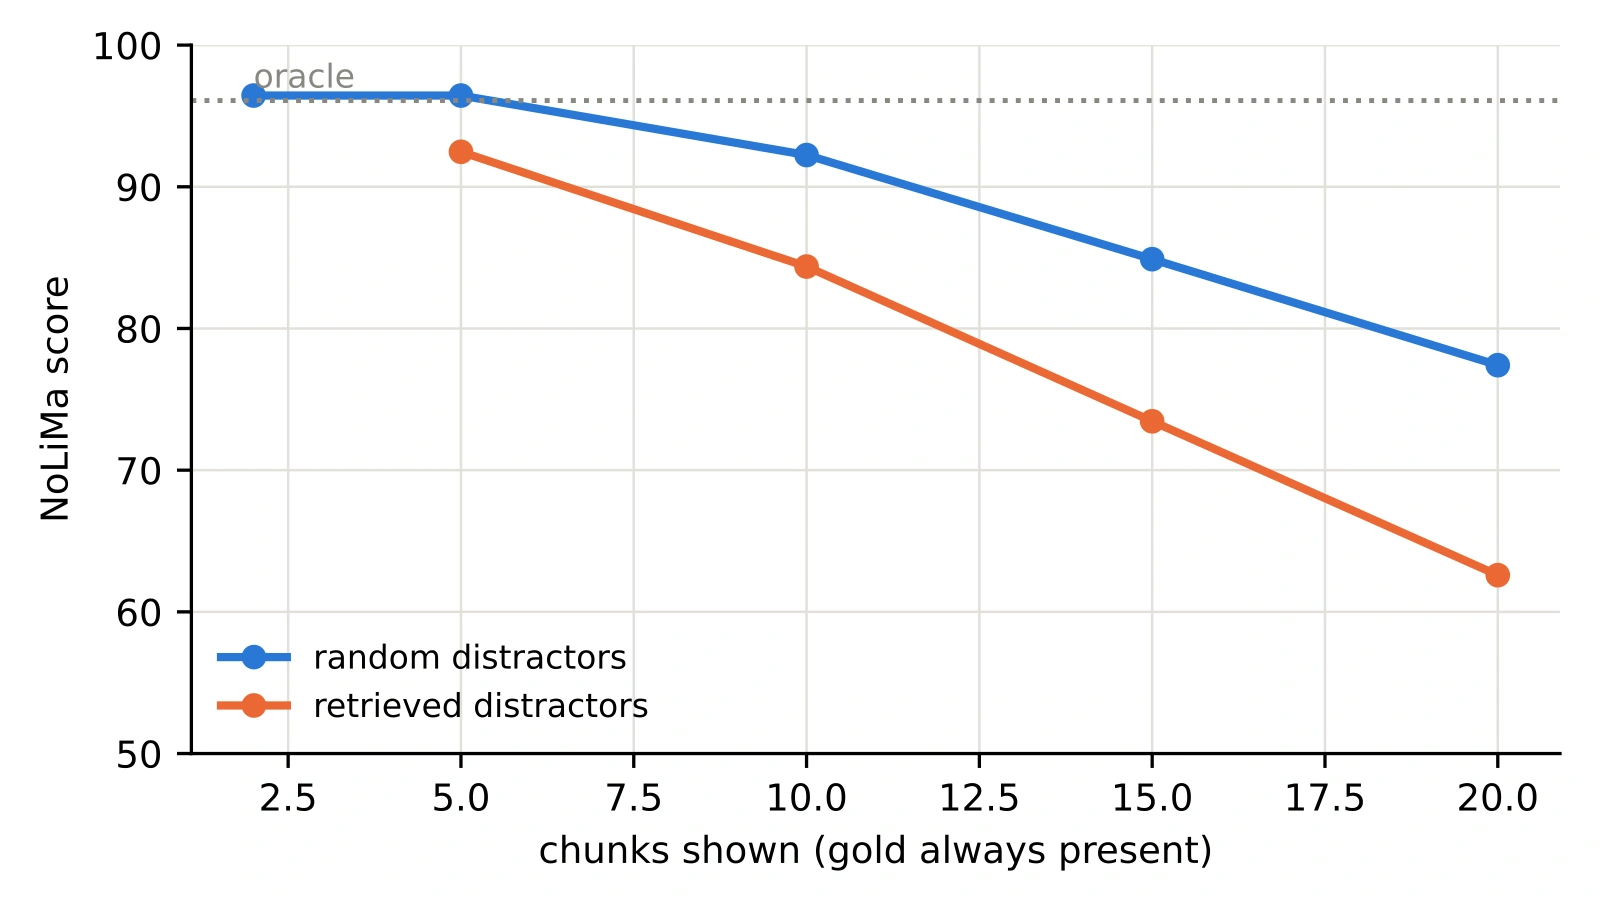
An October 6 preprint introduces UNREAL, which uses a frozen language model to select evidence and answer questions. Training updates fewer than 500000 added parameters.
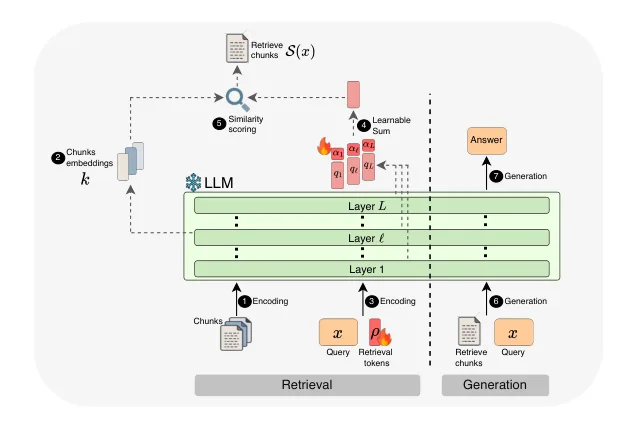
What the results measure
The paper reports a best HotpotQA complete evidence recall of 73.2 percent against a 49.1 percent baseline. This measures whether all required passages appear in the top ten results, rather than final answer accuracy.
Tests focus on sparse evidence tasks. Transfer beyond Wikipedia training to other domains and languages remains untested. The index needs extra storage and still uses BM25 for initial context.
Speed tests used random weights and inputs, with some serving overhead omitted.
Featured chart by Edan Kinderman and coauthors from UNREAL Figure 11, under Creative Commons Attribution 4.0. White margins cropped and converted to WebP.



